Scraping & enrichment
Real Estate Data Engine
A scraping and enrichment platform across six markets, where deterministic extraction does most of the work and a local LLM only handles edge cases.
- Scraping
- Queues
- Local LLMs
- Data enrichment
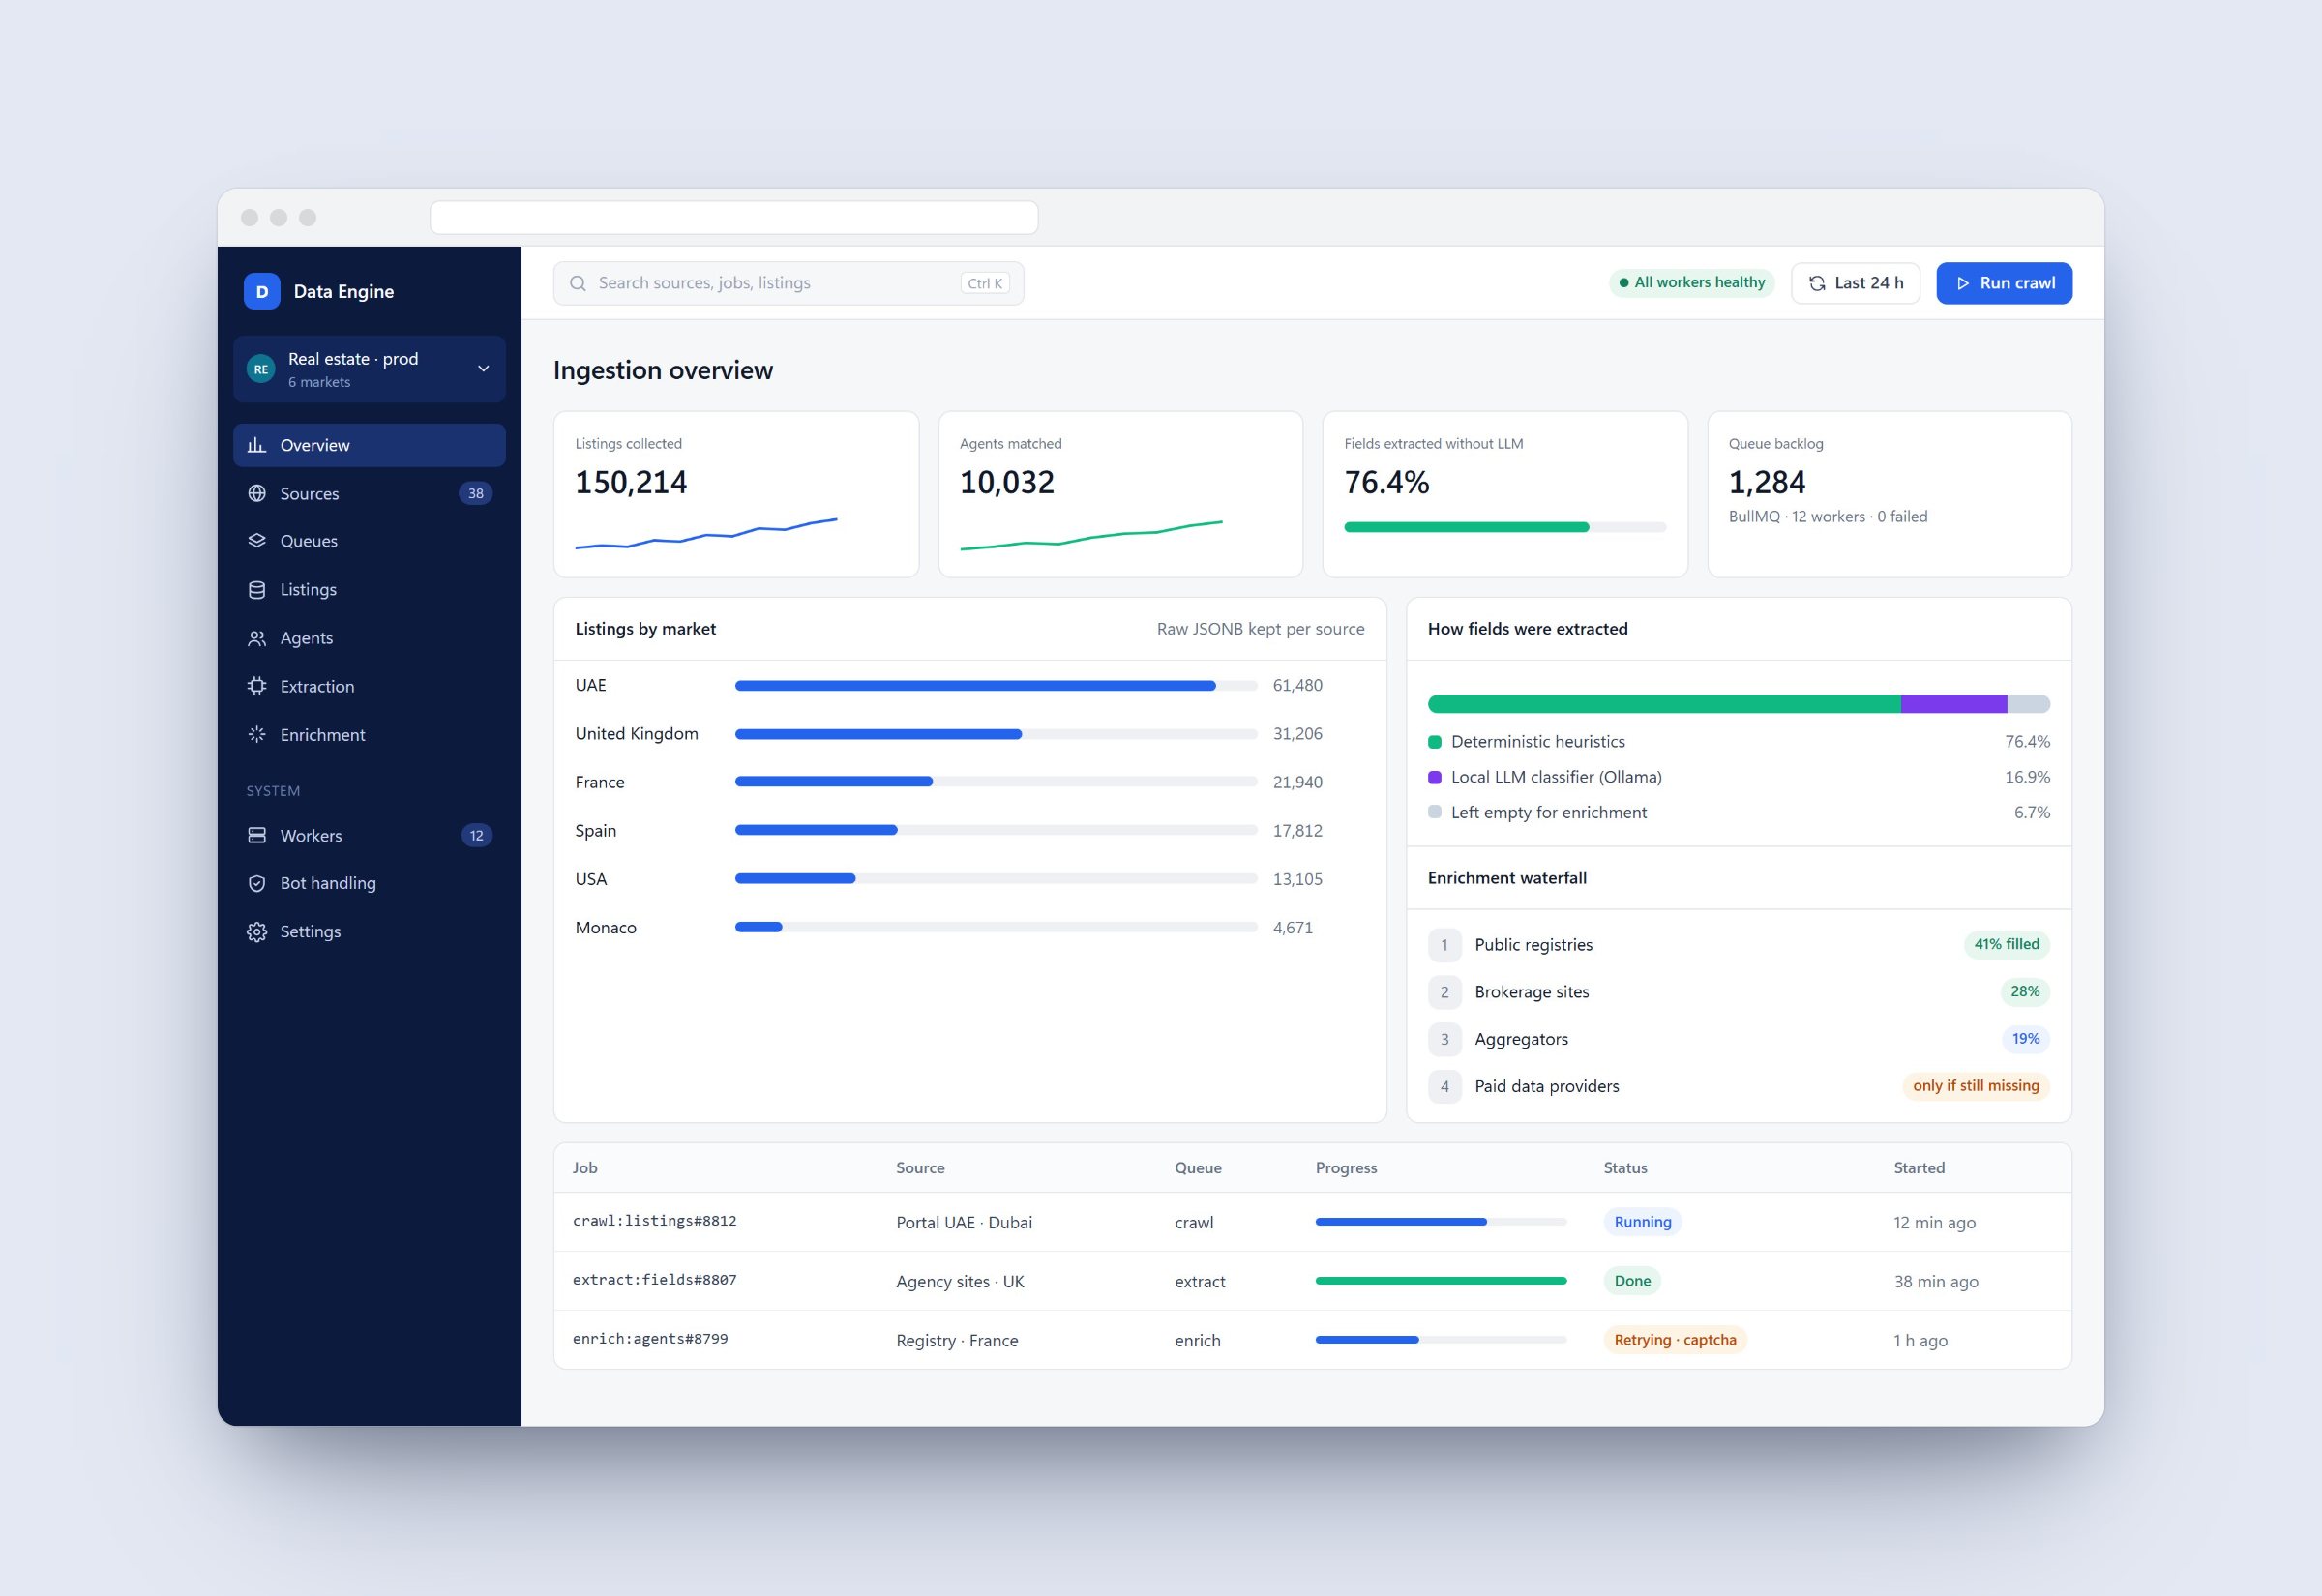
Product screens with sample data. Names and figures inside the screens are illustrative.
01
The problem
Listings and agents across the UAE, France, Spain, Monaco, the UK and the USA, collected reliably and cheaply enough to keep running.
- 150k
- Listings from one source
- 10k
- Agents collected
- 70–80%
- Fields without an LLM
02
What I built
01
Hybrid extraction
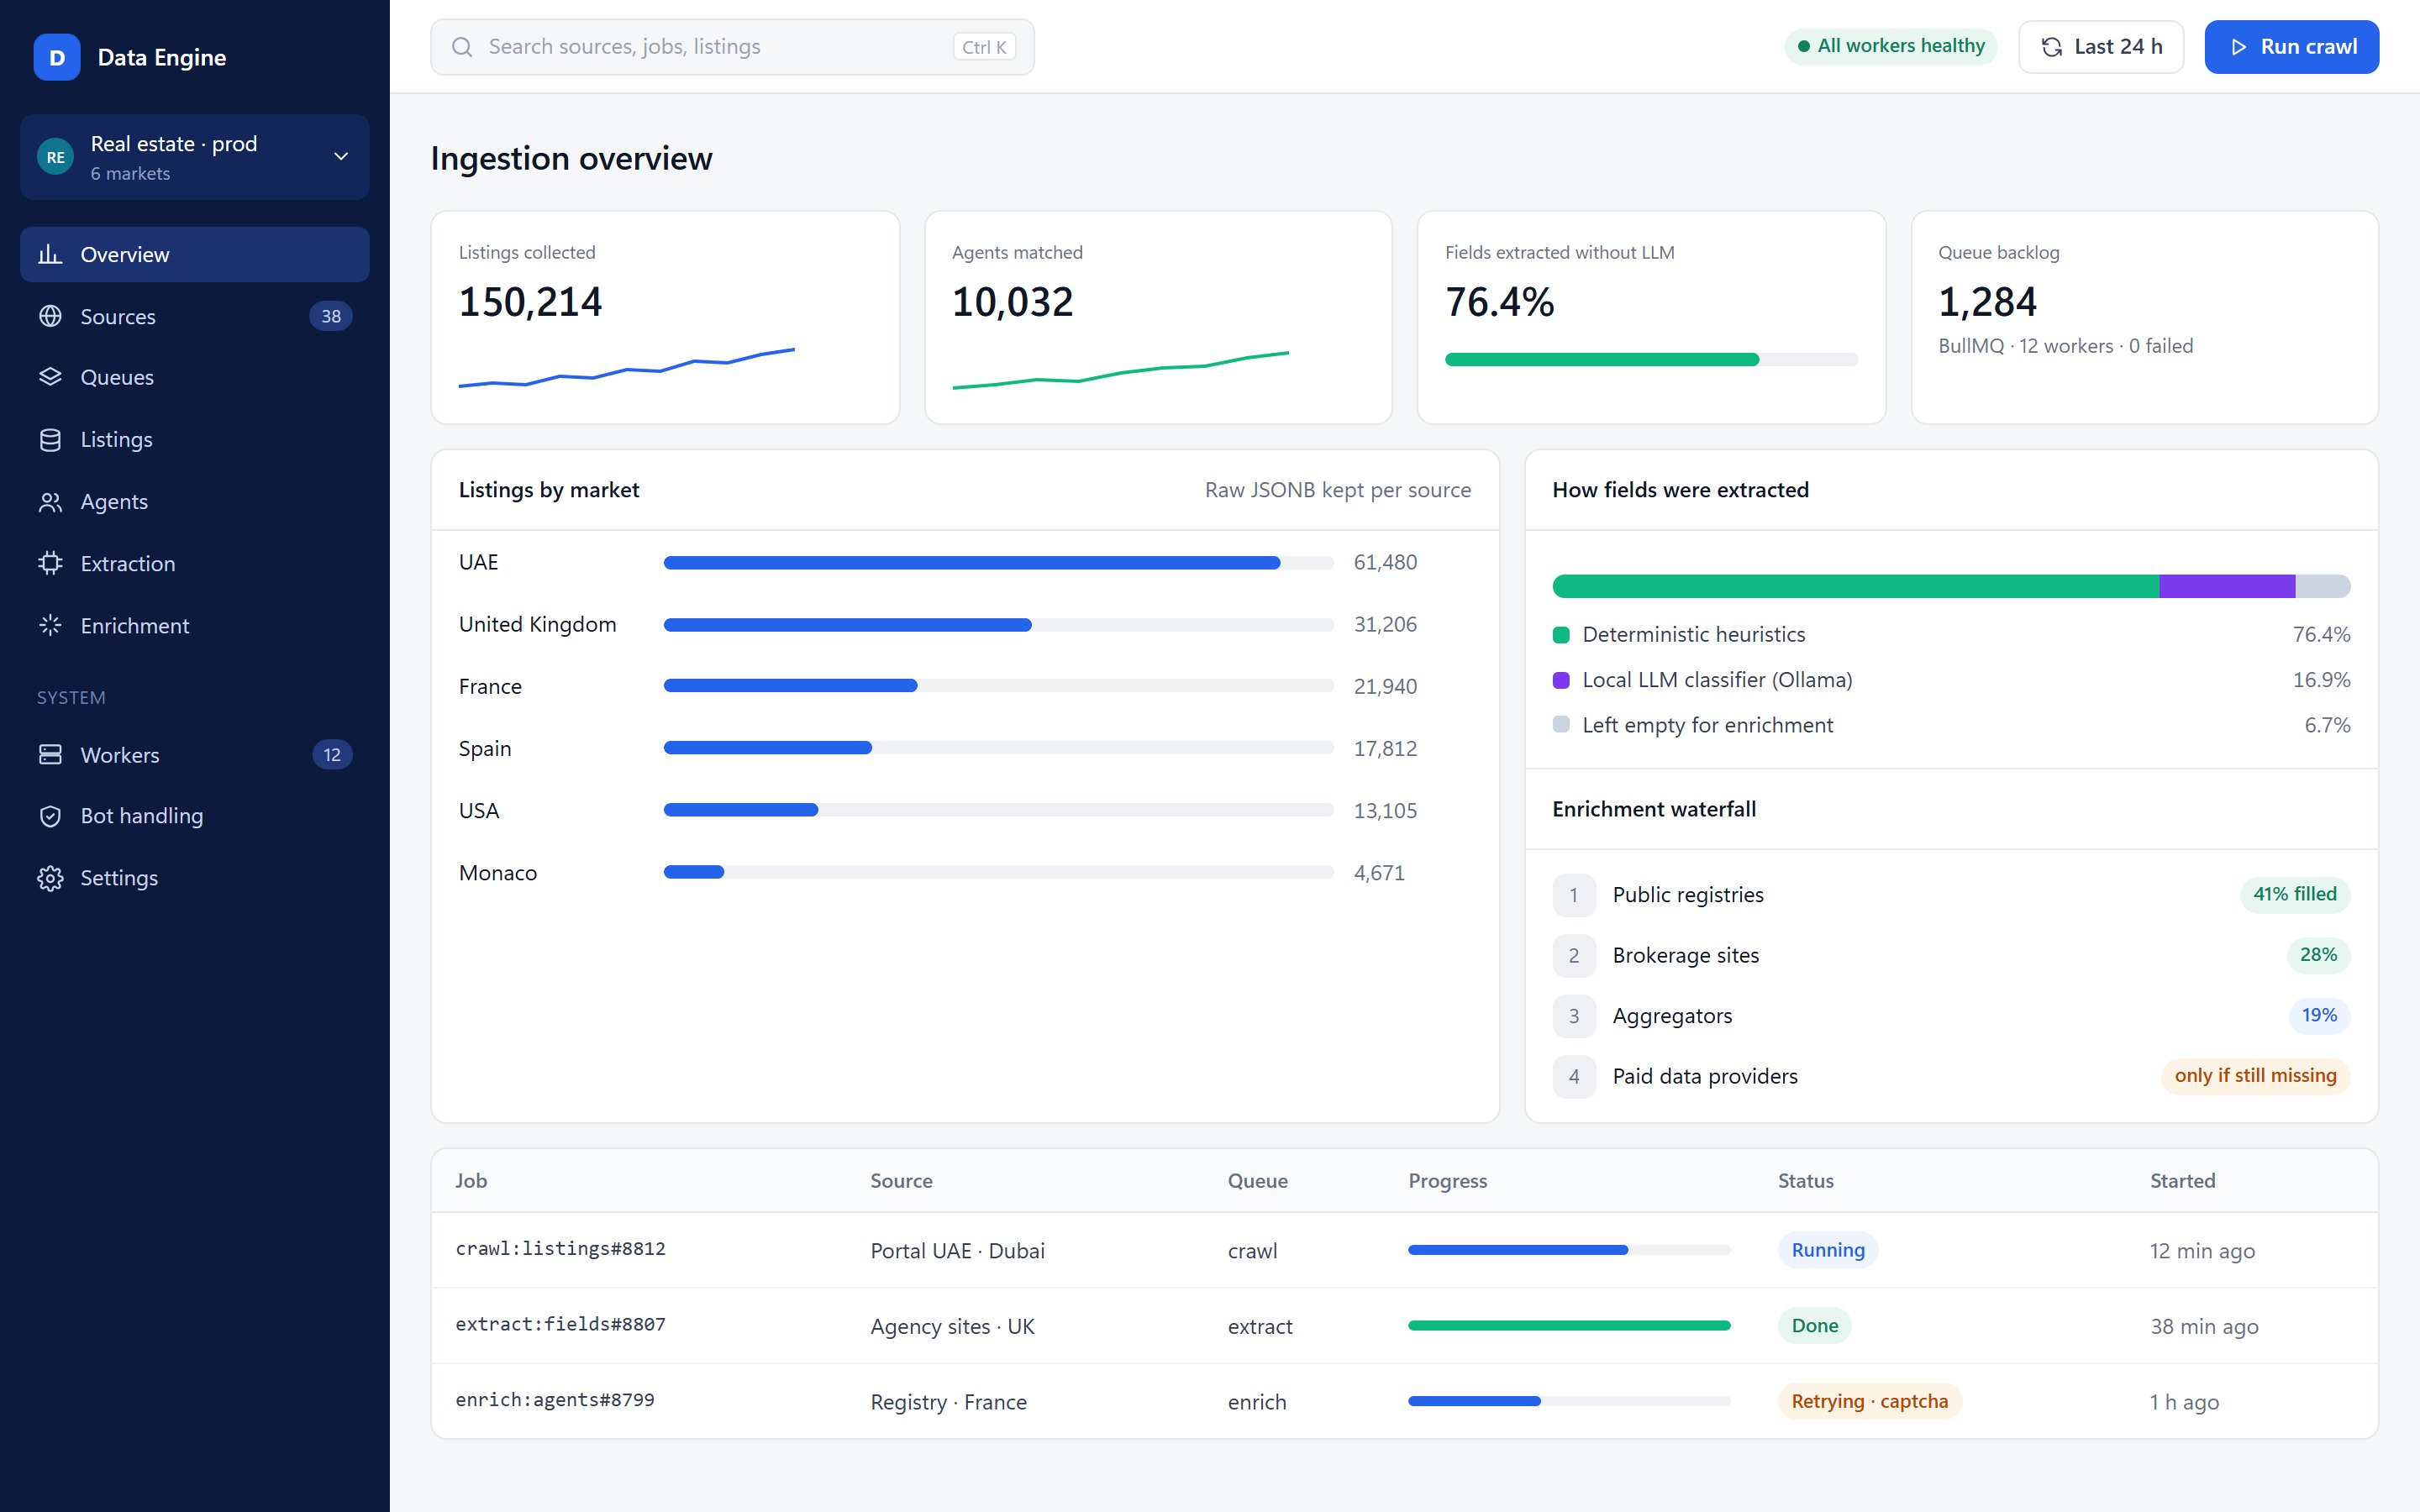
Deterministic heuristics handle 70 to 80 percent of fields. A local LLM through Ollama acts as a narrow classifier for the rest, cutting model cost and variance.
- A Chrome-extension collector proved the approach at 150,000 listings and 10,000 agents
- Waterfall enrichment: registries, brokerages, aggregators, then paid providers
- Raw JSONB stored per source; BullMQ workers with bot-protection handling
03
Key decisions
LLM as a classifier, not a parser
Using the model only where rules fail keeps results predictable and costs low.